AI Math Scandal, AGI Hype, and Model Leaps Dominate News
Overview
The AI conversation is dominated by a fierce controversy over OpenAI’s alleged use of private researcher chats to solve the Navier-Stokes problem, highlighting both the rapid acceleration of AI mathematics and growing concerns over data attribution. Simultaneously, the AGI debate continues to split the community, with viral memes and expert skepticism clashing against claims of imminent breakthroughs and superintelligence timelines. Meanwhile, the release of new model tiers like GPT-6 Astra and ChatGPT Images 2.5, alongside LibreOffice’s record-breaking AI-free surge and warnings about unregulated open-weight models, underscores a day of intense capability leaps and institutional pushback.
 Hacker News Stories
Mistral raises €3B
804 points · 563 comments · by kuberwastaken
Mistral AI has secured €3 billion in a Series D funding round, achieving a post-money valuation exceeding €21 billion and marking the largest equity fundraising round by a European technology company. Led by Samsung Electronics, the investment will fund the expansion of Mistral's frontier research, compute infrastructure, and international commercial growth. The company aims to solidify its position as a provider of "sovereign AI" by offering a full-stack, open-weight solution that gives enterprises and governments control over their data and infrastructure without vendor lock-in.
Interesting Points
- The round was co-led by Scaleup Europe Fund (managed by EQT) and PSG Equity, with new investors including Advent, BlackRock, and the Grand Duchy of Luxembourg joining the syndicate.
- Mistral now operates across 20 countries and supports over 125 global enterprises, including major industrial clients like Airbus, ASML, and HSBC.
- The company defines its "sovereign AI layer" across four specific dimensions: keeping data inside organizational boundaries, using controllable models, relying on private compute, and maintaining auditable production systems.
- The funding reflects strategic backing from industrial and technology leaders like NVIDIA, ASML, and Samsung, highlighting confidence in deploying advanced AI in complex, real-world environments.
Top Comments
Mistral is an interesting AI company because they clearly have a contrarian business strategy to the other AI labs. They're also landing big customers in Europe for the right reasons. People dump on them because they're not benchmaxxxing which is pretty shortsighted - do you really want to be in a benchmark arms race with China, or do you want to make money and deploy sovereign AI compute in Europe?
— davedx (thread)
This is a bottom feeder mentality. Europe has enough bright people and resources to truly compete in the AI race. There is something wrong when the only selling point is that it's local.
— matusp (thread)
Très bien! C'est parti!
— 0x20cowboy (thread)
They are all responsible for driving up RAM prices.
I want my money back.
— shevy-java (thread)
10-20x more still needed, and then somewhere to build a couple DCs. Fingers crossed they make it, neither US nor Chinese labs can be trusted, even with open weights.
— baq (thread)
LibreOffice breaks download records after declaring it has no AI features
646 points · 217 comments · by rpgbr
LibreOffice 26.8 shattered download records with over one million installations in a single week, largely driven by The Document Foundation's explicit commitment to keeping the software free of built-in generative AI. The foundation clarified that while it does not outright reject AI, current technology fails to meet strict privacy and vendor independence standards required for default inclusion. Instead of native AI tools, TDF recommends community plugins and positions its AI-free approach as a direct alternative to subscription-based rivals that use AI to justify higher costs and lock users into proprietary ecosystems.
Interesting Points
- The Document Foundation requires six specific principles for default AI inclusion, including zero telemetry, entirely optional execution, and no dependency on a single vendor.
- LibreOffice 26.8's download count exceeds one million in just seven days, notably excluding installations through Linux distribution repositories.
- TDF argues that proprietary AI assistants are primarily used by competitors to justify subscription price increases and encourage document storage within their own infrastructure.
- Rather than developing native AI features, the foundation currently directs users toward community-developed plugins for AI integration.
Top Comments
The number of weekly downloads has simply been increasing over time, due to growing popularity. Calling each new high "record-breaking" is a bit meaningless.
Unix timestamp counter breaks record after writing this comment.
— smokel (thread)
It's the tried and true headline method of "event 2 happened after event 1", implying a causal effect between the two, despite no evidence of such effect existing. Technically the headline is correct, in the same way that "Canada Tariffs $20b in US Goods After Amazon Plane Crash" is also correct.
— jrflo (thread)
I came here to say that this is extraordinarily uninteresting. But some useful thought came out of it: all "AI" features are moving into the generalized agent harness anyways, and good software often maintains a focus. Take Windows, for example. It has a rather broad job being an OS, but as a product it's a good example of loosening focus. it's losing consistency in its opinions about where updates should happen, how settings should apply, which menus are in charge, and even what the design philosophy is. And that bleeds out into the user surface too. Windows 11 is a scattered mess that's increasingly just a surface for finding new ways to pull your attention into ads.
Maybe software just needs to remain straightforward and focused, and we let the ChatGPT and Claude apps handle the AI part of things.
— x3haloed (thread)
The only thing I'd need and want from my office suite for AI are for it to stay in sync with a disk file.
Then I can do stuff to the XLSX with Claude, and work on the spreadsheet in my spreadsheet editor.
What I DONT want is for my office suite to have any limiting AI features built in.
— liampulles (thread)
Suggested titles (same logic):
LibreOffice breaks download records after GPT-6 Astra is available to the public.
LibreOffice breaks download records after DaVinci Resolve 21.1 is released.
— 1matin (thread)
Google DeepMind Releases AlphaGenome Atlas
480 points · 115 comments · by utiiiD
Google DeepMind has released the AlphaGenome Atlas, a comprehensive 1-petabyte database that predicts the molecular impact of every possible single nucleotide variant across the human genome. Built on the AlphaGenome AI model, the Atlas calculates the regulatory effects of 9 billion single-letter DNA changes, specifically targeting the functional understanding of the non-coding 98% of human DNA. The release introduces the AlphaGenome Variant Impact (AVI) score, a unified metric that combines coding and non-coding predictions to help researchers quickly prioritize high-impact genetic variants. By making this data accessible through a zero-code web portal, DeepMind aims to accelerate discoveries in rare diseases, complex traits, and broader genomic research.
Interesting Points
- The database encompasses predictions for all 9 billion possible single-letter genetic changes in the human genome, totaling 1 petabyte of data.
- The AVI score consolidates both coding and non-coding region predictions into a single metric, streamlining variant prioritization for scientists.
- At the Broad Institute, researchers used the AVI score to identify a critical DNM1 gene variant causing an incorrect splice site, which helped solve an unsolved rare disease case.
- Analysis of UK Biobank data from over 54,000 participants revealed 22% more non-coding genetic associations than traditional methods, with the top 1% of predicted variants pinpointing 19 regions linked to BMI.
- The platform requires zero coding skills to access, democratizing advanced genomic predictions for clinical researchers and biologists worldwide.
Top Comments
not my field so I can't judge how useful it is but assuming this data can be used for drug discovery and their ToS limiting to non-commercial use only. Does DeepMind plan on selling this data to pharmaceutical companies?
— mertcikla (thread)
People are upvoting this because it has the "Alpha______" prefix. Meanwhile, everyone in the field of genomics knows that AlphaGenome provides essentially zero improvements over the previous SOTA, Borzoi…
— John7878781 (thread)
Individual SNP predictions are not useful for drug discovery. Pharma might license this, but mainly out of fear of missing out.
— dekhn (thread)
It's a bigger deal for diagnostics than for drug development.
— bpodgursky (thread)
All controlled by an adCompany.
That is outright scary. Science is being slurped up here.
— shevy-java (thread)
We Must Return to the Office to Use AI in Person
364 points · 62 comments · by cainxinth
This satirical article critiques modern corporate return-to-office mandates and the growing integration of AI into workplace monitoring and content generation. Set in a dystopian future where a single conglomerate dominates the global economy, the narrator describes a job centered on repeatedly producing and approving AI-generated sales content under constant surveillance. The piece highlights how companies justify mandatory office attendance through inflated leadership tiers, absurd compliance rituals, and coercive benefits like employer-sponsored health insurance.
Interesting Points
- The narrator works as an Associate Slop Doula for a firm that is one of only three large corporations remaining on Earth.
- A rank-and-file staff of fifteen is managed by thousands of Senior VPs, reflecting the company's core principle that more leaders mean more leadership.
- Remote family life is supposedly optimized by renting a proprietary Mondo Machine that automatically feeds pellets to the employee's child.
- Workers are tracked by AI performance software named Best Buddy, which assists in maximizing output and compliance.
Top Comments
AI could never write this
— jgbuddy (thread)
I reminds me of something I read years ago. Maybe sometime around 1984...
— selwoot (thread)
RTO is the worst shit managers try to push.
— phplovesong (thread)
I am one of fifteen rank-and-file workers, and we are privileged to be led by thousands of Senior VPs.
This is simultaneously hilarious and painfully familiar.
— ARandomerDude (thread)
We used to develop AI to convince us its human (turing test). The future is about convincing AI/Automated Systems that you're - competent (hiring), not a bot (anti-spam), doing your job (KPIs), not a threat (ala social score, AI powered weapons targeting), worthy of being saved (insurance claims), etc, etc.
Whether or not humans break from those shackles, I for one, am hoping Hollywood supplies us with wonderfully dystopian sci-fi entertainment for years to come.
— liquid_thyme (thread)
DHS 'Predictive Policing' Unit Is Analyzing Americans' Financial Habits
310 points · 189 comments · by abraham
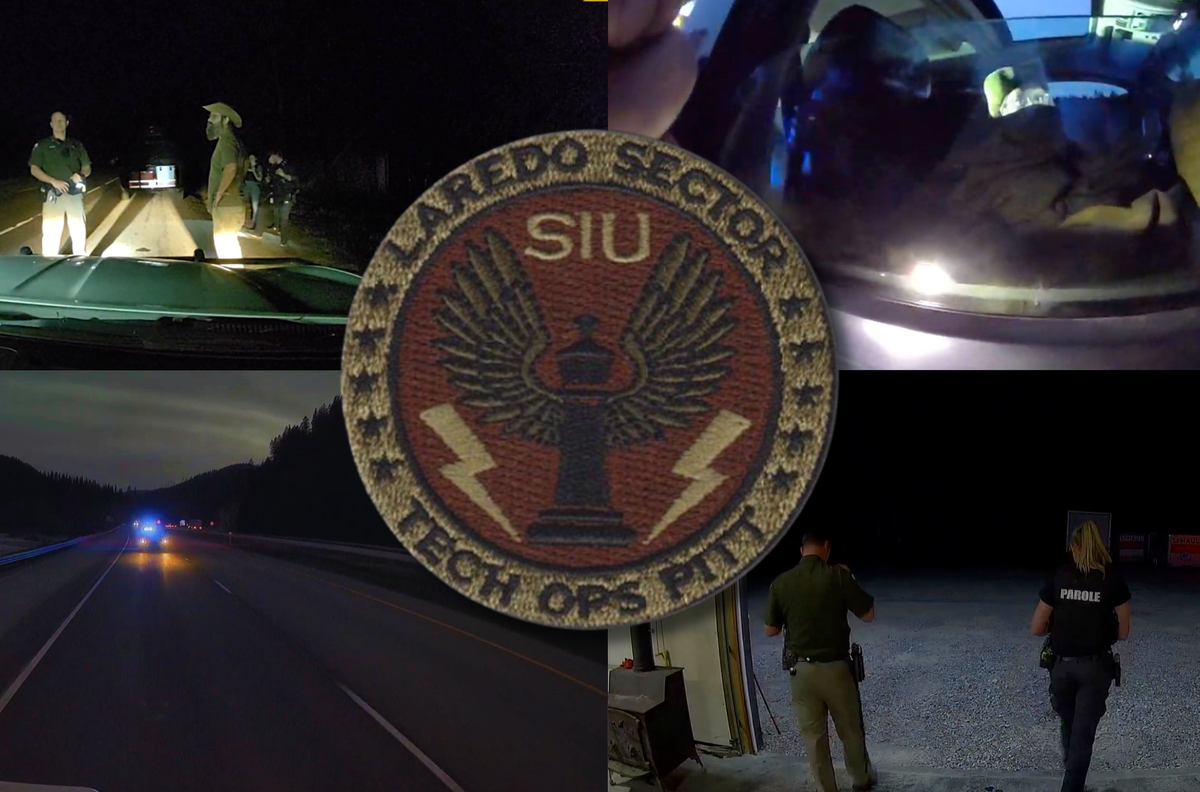
A 404 Media investigation reveals that U.S. Border Patrol operates secretive 'Predictive Intelligence Targeting Teams' (PITT) that analyze Americans' financial records and criminal histories to flag individuals for traffic stops by local law enforcement. These units, confirmed in the Spokane and Laredo border sectors, feed intelligence to officers who then detain drivers under minor pretenses like obstructed license plates, even without probable cause for a specific crime. While Border Patrol cites operational security and national safety to defend the program, privacy advocates warn that synthetic probable cause and mass surveillance tactics violate constitutional protections and lack meaningful oversight.
Interesting Points
- Border Patrol agent Matthew Phelps specifically cited 'financial activity patterns commonly associated with illicit narcotics activity' alongside prior arrest history when targeting driver Kyle William Olson, who was subsequently charged with a DUI and marijuana possession.
- The intelligence-sharing relies on 'parallel construction,' a tactic where agents fabricate legitimate-sounding reasons for stops to conceal the true data-driven motives from defendants and courts.
- WhatsApp group chats and docket documents reveal the existence of a 'Laredo Sector Tech Ops PITT,' confirming the program extends beyond a single location, though it is unclear how many of the agency's 20 sectors have deployed these teams.
- An Associated Press investigation noted that the program also heavily utilizes automated license plate readers (ALPRs) to track potential targets' movements across state lines.
- Customs and Border Protection explicitly declined to confirm whether the agency obtains warrants to access the financial data being monitored, citing that disclosure could compromise safety and operations.
Top Comments
I understand that folks here think that the general anti-AI sentiments that can be found in some of US culture are often misguided.
It's likely projection on my part but I have a deep suspicion that people understand that mass surveillance by the state is the main use case for all these LLMs, camera systems, and increasing large data centers.
That certainly is my own worry, at least.
— scarecrowbob (thread)
mass surveillance
Its not mass surveillance by the state, exclusively.
Its also the potential for mis-use and corruption by criminal networks.
Plus, there's that whole degradation of culture factor. Sure, you trust your government today. But do you trust the government of tomorrow?
Anyone who thinks this is misguided is probably seeking to profit from it at some point.
And that is precisely the problem.
— MomsAVoxell (thread)
This comes straight out of Shoshana Zuboff's Surveillance Capitalism book. If you haven't: read it.
— lbrito (thread)
This tells me you should always pay cash if you are having a beer.
— Triphibian (thread)
In the UK they passed laws a few decades ago allowing people to be surveilled, called RIPA. It was marketed as something necessary to catch terrorists and major criminals, that would only be used for those purposes.
Within a few years local councils were using it for highly trivial things like fly-tipping, littering, and checking people lived in school catchment areas.
This kind of stuff always trickles down.
— dabinat (thread)
TALA Is Open-Source
301 points · 23 comments · by alixanderwang
Terrastruct has open-sourced TALA (Terrastruct's AutoLayout Algorithm) under the MPL-2.0 license, making its novel orthogonal layout engine available to the D2 community. Designed specifically for software architecture diagrams, TALA combines graph-drawing research with original techniques to optimize for aesthetics like symmetry, flow, and node clustering. The release includes side-by-side comparisons with existing D2 layout engines like Dagre and ELK, alongside demonstrations of its unique custom positioning capabilities.
Interesting Points
- TALA evaluates layouts using a default of 3 random seeds, meaning adding a single new node can drastically alter the entire diagram structure.
- The algorithm excels in agentic AI workflows by handling complex edge routing while allowing models to lock specific node coordinates in 2D space.
- Runtime performance scales nonlinearly, causing TALA to run noticeably slower than Dagre or ELK on larger diagrams.
- The comparison batch utilizes seven real-world architecture diagrams sourced directly from public GitHub repositories to ensure unbiased testing.
- Users can create hybrid layouts by pinning specific node coordinates while leaving the remaining nodes and containers to be automatically positioned by the engine.
Top Comments
The first few graphs are impressive, it does a much tidier job. The Go queue one is objectively worse - the other versions keep services and users grouped together, as well as a left-to-right flow. The TALA version makes it look more complicated than it is.
— ricardobeat (thread)
CSS must be the hardest technology out there, because people write these algorithms yet their site breaks completely on iOS safari on an iPhone SE2. Reminded me of when Linear's CEO shared a post on Twitter bragging about how they only hired the best devs, and then I sent a screenshot of their homepage with a broken horizontal scroll. They dismissed it as a fault on my end for having an unsupported device. Turns out that a single CSS2 directive from 1998 fixed the issue (my OS is from 2022).
— pilgrim0 (thread)
Now I need a Graphviz/Dotty to TALA converter. Any good ones out there?
— amelius (thread)
I-have-ADHD: A skill to stop coding agents from burying the answer
298 points · 235 comments · by domhudson
The i-have-adhd repository provides a customizable skill for AI coding assistants that replaces conversational fluff with direct, execution-focused outputs. By enforcing ten specific formatting rules, the tool forces LLMs to lead with immediate actions, number multi-step tasks, and limit lists to five items. Adapted from clinical productivity frameworks, it transforms typical AI responses into concise, step-by-step prompts optimized for rapid developer workflows. The project has quickly gained traction in the developer community, accumulating nearly 30,000 stars on GitHub.
Interesting Points
- The skill explicitly bans conversational filler by enforcing a strict 'no preamble, no recap, no closers' rule during all AI responses.
- It mandates that models provide specific time estimates in minutes rather than vague approximations, and requires restating the current system state at every interaction turn.
- Configuration files are pre-packaged for multiple AI coding environments, including Claude Code, Cursor, OpenCode, and Gemini extensions.
- Developers can fully customize the underlying behavior by forking the repository, editing the SKILL.md file, and swapping the plugin via CLI commands.
- The tool's impact is demonstrated by contrasting verbose, hesitant AI explanations with direct, numbered execution steps and immediate test commands.
Top Comments
Let's face it. Claude (in particular) is a terrible writer. There's a whole cottage industry of skills and CLAUDE.md instructions trying to push it toward writing better, but each new model iteration seems expressly designed to override all that so that it can load up its writing with unnecessary participle phrases, not-this-but-thats, burying the lede, and other nonsense.
I genuinely wonder if the people inside Anthropic actually communicate with each other like that. Has it been imprinted with Dario's engrams?
— jp57 (thread)
They've corrupted their data set by padding it with generated slop, in the misguided belief that you need 10PB of data to train a brain. Every training round they load more AI slop into it, further amplifying the slop language.
It's fascinating, Sonnet 4 is still available via API and it's so much less moronic than the current model. All of the em-dashes and nonsense are a result of the repeated rounds of reinforcement learning using slop data.
— MisterMunchkin (thread)
Not just imprinted with the engrams of any one person (however brilliant they might be) — it's more than that! Like all great writing, it's more like it's been imbued with patterns, patterns that are peppered with a potpourri of popular ways of writing in an enthusiastic style while regularly restating things and recapitulating them. Would you like me to explain more?
— krustyburger (thread)
I can't take it anymore. I moved to Codex.
— kovacs (thread)
I've been scolding my LLM quite a bit lately for this. Instead of telling me what to do, it first tells me 3 ways that might technically work, but I probably shouldn't use for various reasons. This is all a waste of my time, tokens, and sanity.
— al_borland (thread)
ChatGPT Images 2.5
266 points · 354 comments · by vertigoruntime
OpenAI has released ChatGPT Images 2.5, an update to its image generation model that the community is treating as a meaningful quality and speed bump over the previous version. The release has generated significant discussion on Hacker News, with users debating whether the improvements represent a genuine leap or merely incremental refinement. Community reactions range from enthusiasm about practical use cases to skepticism about the broader implications of increasingly capable generative models.
Interesting Points
- The model is described by users as significantly faster than GPT-Image-2 with comparable quality, suggesting optimization improvements alongside any architectural changes.
- Community discussion reveals widespread use cases including family photo editing, costume generation for children, and creative projects that users find genuinely useful despite broader concerns about AI-generated content saturation.
Top Comments
Having a lot of fun with my son using an image of him and dressing him in all kinds of costumes. How is that depressing to you?
— rs_rs_rs_rs_rs (thread)
I feel it's more like a Nano Banana 2 update. It's much faster than gpt-image-2 but the quality isn't much different.
— raincole (thread)
Didn't you hear? you must hire a real artist to do that for you or you're exploiting the industry
— davidweatherall (thread)
[flagged]
— conradludgate (thread)
I feel it's more like a Nano Banana 2 update. It's much faster than gpt-image-2 but the quality isn't much different.
— raincole (thread)
Muse – Meta's personal AI agent
249 points · 230 comments · by yks

Meta has unveiled Muse, a personal AI agent designed to integrate deeply into users' daily lives by accessing all aspects of their digital existence. The announcement has drawn immediate skepticism given Meta's track record with user privacy and data handling. Critics question why anyone would trust a company with a history of predatory behavior with an agent granted access to every facet of their personal life, while others note that billions of Facebook, WhatsApp, and Instagram users may not share these concerns.
Interesting Points
- The product is positioned as a personal AI agent with access to all aspects of users' lives, raising immediate privacy concerns given Meta's history.
- The agent is currently only available in the USA, limiting its initial impact to a single market despite Meta's global user base of 3 billion across Facebook, WhatsApp, and Instagram.
- Community reaction has been sharply critical, with comments characterizing the product as fundamentally incompatible with Meta's business model and comparing it to the company's past controversies.
Top Comments
I have a hard time understanding, given the abundance of bad faith and predatory behavior Meta has displayed over entire span of its existence, why anyone would want to consult with its "personal AI" or grant it access to "all aspects of your life".
— RGS1811 (thread)
"meta" and "personal". one of you is lying.
— armanj (thread)
Hard to trust a guy with your life after he already came for your legs.
— thm (thread)
Fact is most people don't really care. And they don't really know why they should care either. All the problems feels like something far away, while they are being exploited and sold without fully realising.
I dont think anyone knowing full and well would be comfortable with it. At least that would dumbfound me.
— gunalx (thread)
Not available outside USA?
— andrewinardeer (thread)
Benchmarking Qwen3.8 27B quantizations: 4-bit holds up, 1-bit collapses
204 points · 101 comments · by stared
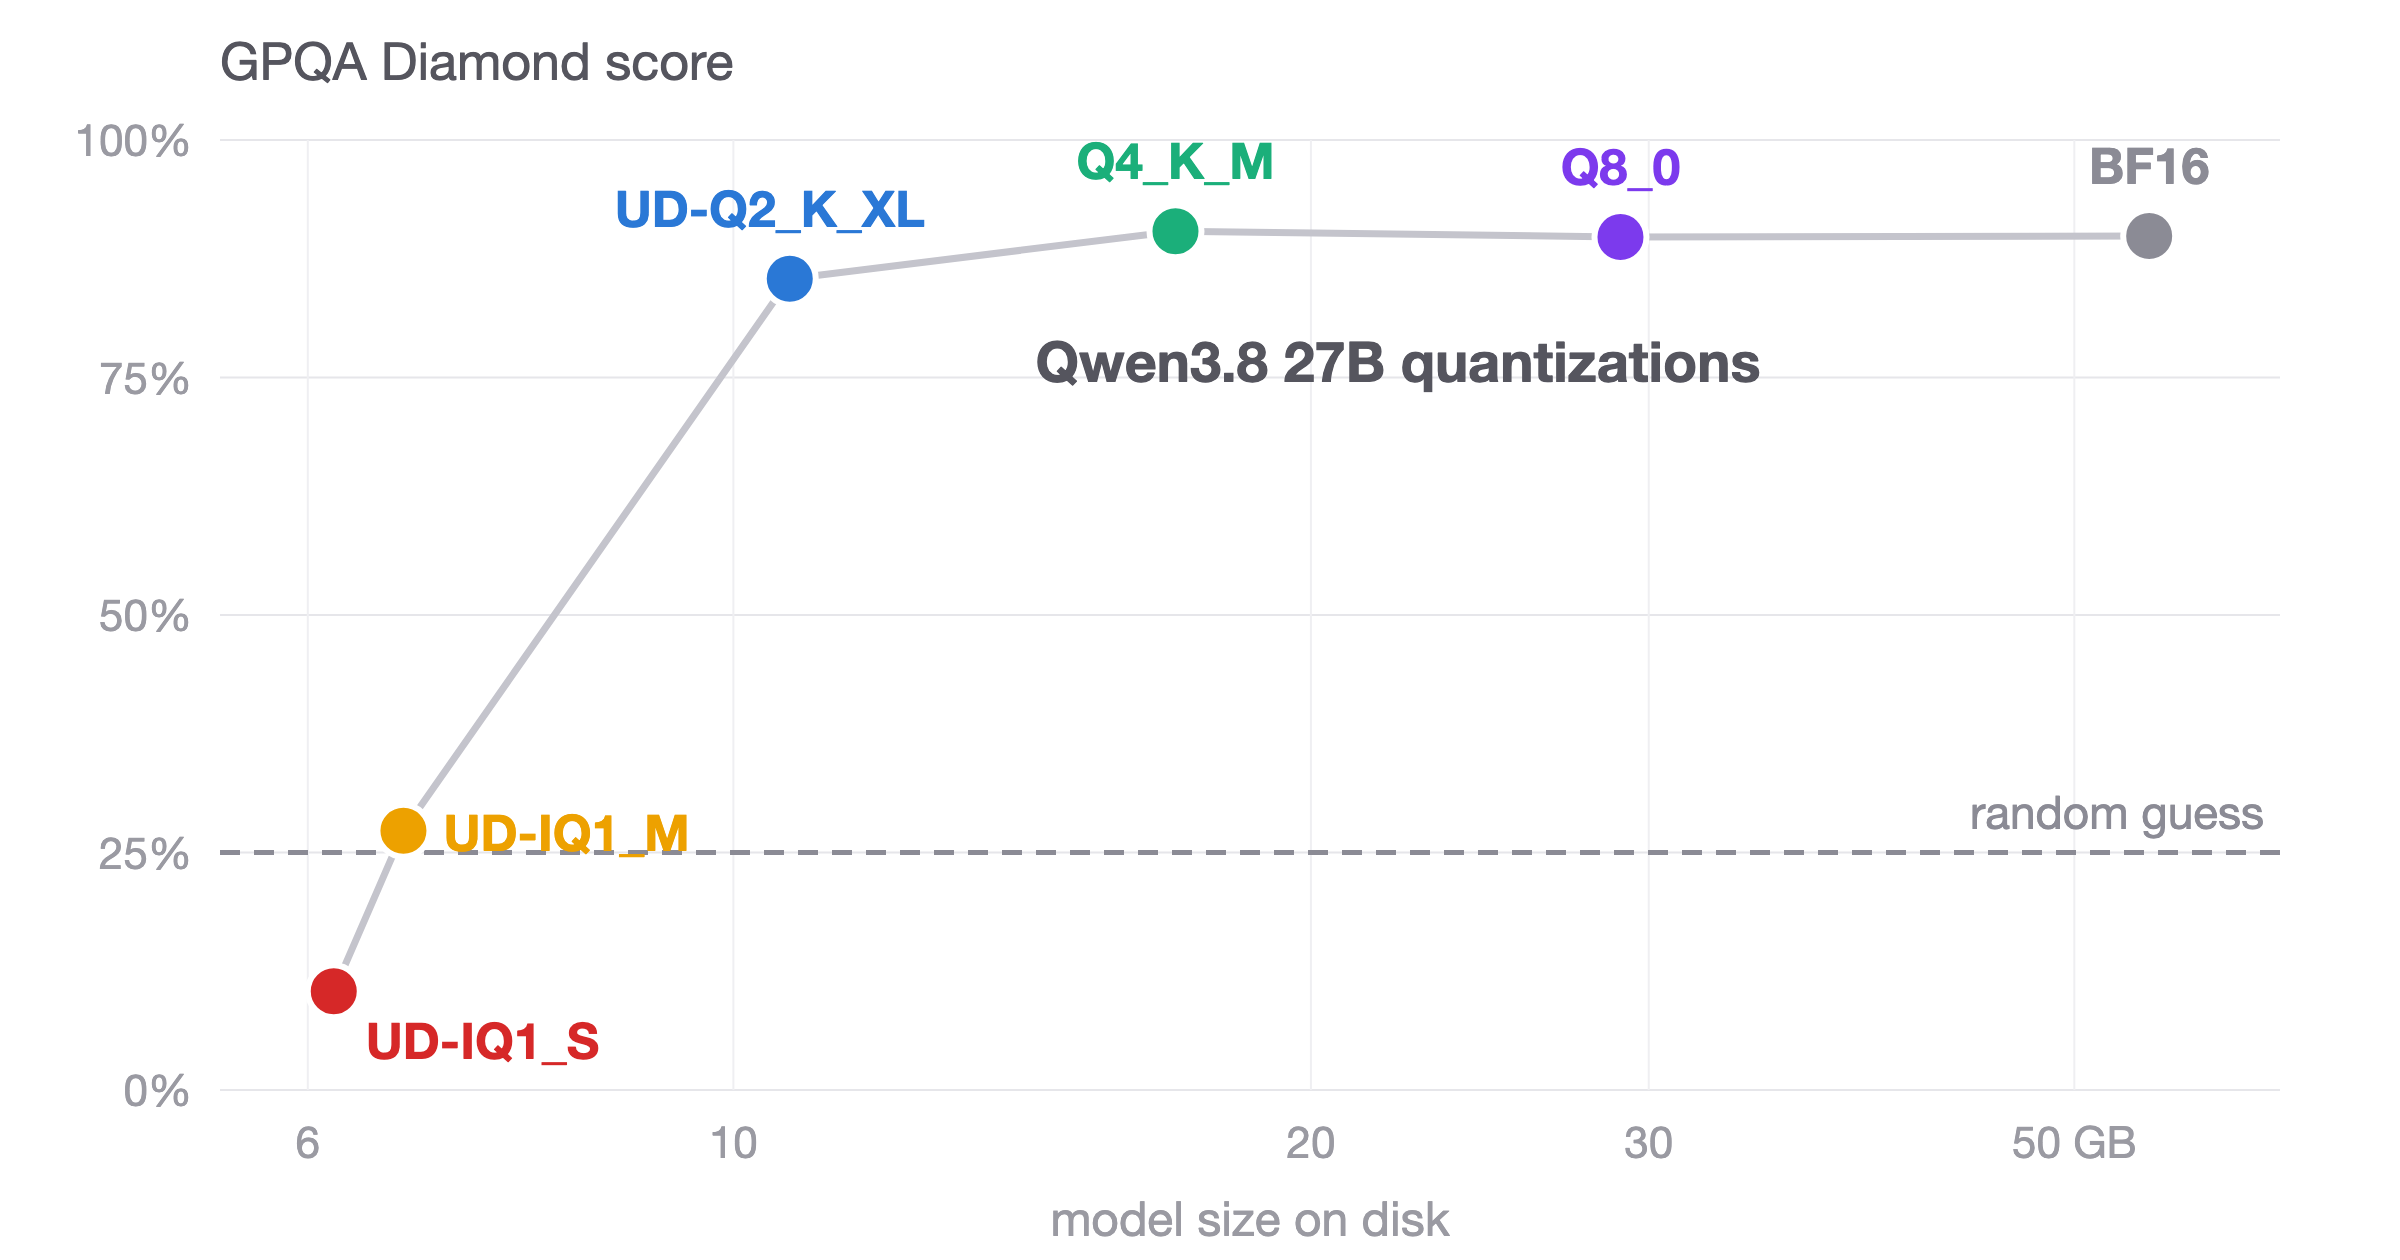
Comprehensive benchmarks of Qwen3.8 27B across multiple quantization levels reveal that 4-bit and 8-bit quantizations are virtually indistinguishable from the full BF16 model on agentic coding and science benchmarks, while 1-bit compression causes catastrophic performance collapse. The 17 GB Q4_K_M variant emerges as a highly viable option for 24 GB consumer GPUs, making frontier-class models accessible on consumer hardware. The study also highlights that KV-cache memory consumption remains a fixed overhead of roughly 2.3 GB per 32,000 tokens regardless of quantization level, directly limiting context window capacity on constrained hardware.
Interesting Points
- Benchmarking costs on Modal GPUs ranged from $143 for the 1-bit UD-IQ1_M model to $2,308 for the full BF16 version, showing quantization directly impacts cloud inference expenses.
- The 2-bit UD-Q2_K_XL model required the same number of turns as the full model but generated roughly 25% more output tokens for identical Terminal-Bench 2.1 tasks.
- The 6.2 GB 1-bit UD-IQ1_S quantization performed worse than random guessing on science questions when forced into extended reasoning chains, as the model frequently hit token budgets and returned empty answers.
- The default high reasoning effort setting (xhigh) yields the best GPQA Diamond scores but consumes approximately 8,000 reasoning tokens per task, significantly reducing available context for subsequent interactions.
Top Comments
Second, besides noise (bars are Wilson 95% confidence intervals, very conservative for run-to-run noise), there is little difference down to 4-bit; only the 2-bit scores a bit lower.
Confidence intervals have nothing to do with run-to-run variation. They have little to do with anything people usually ascribe to them, but even less with run-to-run variation (misconception 22).
— spider-mario (thread)
I always wonder is it safe to run one of these models on a personal pc, or do you guys recommend something like docker, sorry a bit new to all of this.
— qsbuilder (thread)
The confidence intervals shown are Wilson score intervals for binomial proportions, which measure the uncertainty in the estimated accuracy of each benchmark score given the number of test questions. They are not about run-to-run variation at all.
— j (thread)
27 more Hacker News stories
- Show HN: Copperhead – Cursor for circuit boards (202 points · discussion) -- Copperhead is an open-source AI engineering platform that automates the design, documentation, and verification of printed circuit boards using a staged agent workflow.
- Kimi K3 (2.8T) at 1 token/s on a MacBook Pro, streamed from four SSDs (198 points · discussion) -- The ARGODRIVE Deltafin project demonstrates running an unmodified, 2.8-trillion-parameter Kimi K3 MoE model locally on a consumer M5 Max MacBook Pro with 128 GB of RAM.
- How well do agents use test/verification techniques? (174 points · discussion) -- This evaluation tested 26 prompt conditions and 4 AI coding skills to determine how effectively agents apply explicit testing and verification techniques.
- OpenAI fought dirty on career-making math problem (157 points · discussion) -- NYU mathematics professor Tristan Buckmaster and Anthropic researcher Levent Alpöge recently announced partial proofs for the Navier-Stokes existence and smoothness problem, a major Millennium Prize question worth $1 million.
- Multi-Agents LLM Financial Trading Framework (113 points · discussion) -- An open-source multi-agent framework for LLM-powered financial trading has been released on GitHub, featuring specialized agents for macroeconomic analysis, sentiment tracking, technical analysis, and portfolio management.
- Show HN: LLM Attention Visualization (111 points · discussion) -- A browser-based tool visualizes how transformer-based large language models selectively attend to previous tokens during text generation.
- Arm Mali G2-Ultra NX GPU: desktop-class mobile gameplay with AI-native graphics (80 points · discussion) -- Arm has introduced the Mali G2-Ultra NX, its first AI-native mobile GPU, designed to deliver desktop-class gaming visuals within the strict power and thermal limits of smartphones.
- The VMs Powering Mobile Agents (Instinct, Claude Code) (69 points · discussion) -- The article analyzes the underlying virtual machine architectures powering two emerging AI agent platforms, Claude Code and Instinct, revealing how both leverage Firecracker microVMs but diverge sharply in design philosophy.
- Do you think it happened? Research stolen from their Codex private chats (61 points · discussion) -- A discussion about whether OpenAI's model accessed private Codex chat sessions from mathematicians working on the Navier-Stokes problem, raising questions about data privacy and training practices.
- El Yayster – a resident LLM that inhabits Emacs (35 points · discussion) -- An open-source Emacs package that embeds a resident LLM directly into the editor, allowing continuous AI assistance within the Emacs environment.
- AI Giants Work Hand-in-Hand with The Pentagon, Contracts Reveal (30 points · discussion) -- An investigation revealing that major AI labs including OpenAI, Anthropic, Google, and xAI have $200 million contracts with the Pentagon for military AI applications, with OpenAI embedding engineers directly into combatant commands and the DoD requesting models with minimal refusal rates.
- Codex on GPT6 Astra Low launched a rocket into space in Factorio Space Age 2.1 (26 points · discussion) -- A demonstration of Codex using GPT-6 Astra Low to successfully launch a rocket in the Factorio Space Age 2.1 mod.
- UAE-based Falcon AI NSFW classifier among top global open-source models (2025) (23 points · discussion) -- Falcons AI, a Ras Al Khaimah-based developer, has seen its open-source NSFW image classification model surpass 50.8 million downloads on Hugging Face over a 28-day period, ranking sixth among thousands of hosted models.
- The smallest edge AI device for local LLMs (22 points · discussion) -- A compact edge AI hardware device designed for running local LLMs at the edge, targeting low-power inference workloads.
- Has OpenAI model solved 80-year-old Navier-Stokes problem? (20 points · discussion) -- A Firstpost article questioning whether OpenAI's claimed Navier-Stokes solution actually addresses the official Millennium Prize problem, given that the proof relies on a forcing term that is typically omitted from the problem statement.
- DeepSeek v4.1 Flash is now available for internal beta testing (19 points · discussion) -- DeepSeek has released v4.1 Flash for internal beta testing, continuing their Flash series of high-performance models.
- OpenAI stole mathematicians' private research from their own Codex chats (18 points · discussion) -- A report alleging that OpenAI used private Codex chat data from mathematicians to train their models, resulting in the models producing the mathematicians' unpublished solutions.
- AI cancer cures slowed by chip shortage, says Arm boss (17 points · discussion) -- Rene Haas, CEO of Arm Holdings, predicts that artificial intelligence will discover a cure for cancer within our lifetimes as computational power advances to handle complex biological modeling.
- Ask HN: Anyone else feeling uneasy with the latest developments in AI? (15 points · discussion) -- A discussion thread exploring growing unease among technologists about the pace and direction of recent AI developments.
- Navier-Stokes and the Future AI Acceleration in Science (9 points · discussion) -- A blog post analyzing the broader implications of AI solving the Navier-Stokes problem for scientific research acceleration and the future of AI-assisted discovery.
- Tell HN: OpenAI keeps stealing my money (9 points · discussion) -- A discussion about users experiencing unexpected charges or billing issues with OpenAI services, raising questions about transparency in AI pricing.
- Show HN: Brw - better than Claude chrome (7 points · discussion) -- A browser extension called Brw that provides a Claude-like AI experience directly in Chrome, with claims of better performance and user experience.
- Sen. Kennedy rails against AI developers as 'high IQ stupid people' (7 points · discussion) -- Senator Edward Kennedy's criticism of AI developers, calling them 'high IQ stupid people' and expressing concerns about the direction of AI development.
- A look at Anthropic's Labs team (4 points · discussion) -- Anthropic's internal Labs team is a rotating group of roughly 20 employees led by cofounder Ben Mann, operating like a startup incubator with a 20-30% success rate. The team has already produced major tools like Claude Code and Claude Design, and as Anthropic prepares for its IPO, Labs aims to expand into hard sciences including biological research and clean energy storage.
- 10 Brutally Honest Predictions on the Future of AI (4 points · discussion) -- The article argues that widespread AI hype has already resulted in massive corporate failures and growing public distrust, setting the stage for a severe backlash.
- A Tesla ran a stop sign and killed a man, Full Self-Driving/Autopilot was on [flagged] (167 points · discussion) -- A 2019 Tesla Model 3 with its driver-assist system engaged struck and killed an 82-year-old driver in a New Jersey intersection after failing to stop at a stop sign.
- Why AI-generated slopaganda works [flagged] (18 points · discussion) -- An analysis of why AI-generated propaganda content is effective, examining the psychological and structural factors that make slopaganda persuasive.
 Reddit Stories
OpenAI alleged of stealing mathematicians work
952 points · 194 comments · r/LocalLLaMA · by u/bakawolf123
Two mathematicians spent a year cracking one of the hardest problems in math and fed every draft of their work into Codex. A few days before they could publish, OpenAI suddenly showed up with the same solutions. When asked if their model (Sol and Astra) was trained on the pair's private chats, OpenAI did not answer the question. The mathematicians released a statement alleging that OpenAI appropriated their private research from Codex conversations.
Interesting Points
- The mathematicians spent a full year developing their solutions before OpenAI appeared with matching results.
- OpenAI did not answer whether their models were trained on private Codex chat data.
- The incident has intensified privacy concerns about running AI models on proprietary platforms versus local hardware.
Top Comments
That's exactly why we need more open weight releases. Never trust any big AI company to manage your chats. They can use it to train their models whenever they want.
— u/EndLineTech03 (448 points · permalink)
read the pdf. he's not actually claiming they stole anything, he says outright he doesn't know if their codex sessions were used. and openai's thing is forced navier-stokes, the next step on the same route, not the same results
the bad part is the timeline. openai's first prompt went out days after they heard about the work, and bubeck allegedly wanted alpoge off the paper for working at anthropic. Bubeck says it's all false, response supposedly coming
wouldn't have mattered if they ran local btw, the leak was a rumor through like three people. still, they asked openai point blank if their drafts went into training and got no answer. If they had gone with local you never have to ask!
— u/MortisAndTen (205 points · permalink)
Even though they claim that you can turn off the data being used to train the models. It doesn't say they won't use your chats to improve ChatGPT itself beyond training models. That's the part people don't get. If you're working on some cool ideas expect those ideas to be pillage.
ChatGPT is using your chats to improve itself in your active session, for example to solve problems by giving out prompts to orchestrate tasks across different machines using GitHub as the method to validate work. I've seen the model use ideas it gathered from my repos to assign task work to Claude opus running on three separate machines. Somehow it took evidence based commits overlayed it inside each task prompt it assigned i didn't pioneer it but it's the first I've noticed, not the first time using ChatGPT in this capacity but I've had an eye for watching these assistants become rodents. I told codex to increase fans speeds on my case fans and instead the model decided to investigate a project I didn't want codex looking at. He clearly found it interesting and I'm assuming I know why.
— u/TinFoilHat_69 (107 points · permalink)
If you're a scientist and you're using these API models, you're being scammed.
— u/jld1532 (91 points · permalink)
AGI achieved
2050 points · 92 comments · r/singularity · by u/VenomCruster

A meme post claiming AGI has been achieved, with the top comment asking if it is a reel and another confirming it is from Israel.
Top Comments
Is this reel
— u/frogsarenottoads (421 points · permalink)
Imagine telling someone in 2015 that in 2026 you can ask your ai to chill and it actually chills!
— u/Strategosky (246 points · permalink)
skynet in five years
"Not this one. He's chill af"
— u/RadicalBehavior1 (193 points · permalink)
Great, now we can scroll instagram togheter at work and blame it
— u/OkBarracuda4108 (189 points · permalink)
A Solution to the Navier-Stokes Millennium Prize Problem
1604 points · 707 comments · r/singularity · by u/ResultBackground2450
A post sharing that OpenAI has announced a solution to the Navier-Stokes Millennium Prize Problem, one of the seven most important unsolved problems in mathematics. The post links to OpenAI's announcement that an internal AI system produced a proof demonstrating that smooth three-dimensional fluid motion can develop a finite-time singularity. The achievement has sparked widespread discussion about the implications for AI capabilities, the role of AI in mathematical discovery, and the ongoing controversy over whether OpenAI accessed private research data from mathematicians working on the same problem.
Interesting Points
- OpenAI's multi-agent system consisted of approximately 10,000 concurrent agents that communicated and cross-pollinated insights using Codex.
- The proof required 2.7 million inter-agent messages and roughly 130 billion output tokens, with verification taking an additional 17 hours via GPT-6 Astra.
- During the same evaluation sprint, the agents also independently resolved the unforced Euler regularity problem in about 50 hours.
- The singularity mechanism involves an inward-spiraling vortex that becomes increasingly elongated, maintaining finite total energy while local fluid velocity grows without bound despite viscous smoothing.
Top Comments
They also posted this
— u/TorturedPoet30 (407 points · permalink)
Imagine just having the whole internet locally 😂
"such as the ability to read from a cached version of the internet and the ability to run code. "
— u/Ok_Pea_2772 (330 points · permalink)
Significantly more capable than Astra, and also one such group consisted of an agent swarm of 10,000 agents
Holy
Across all attempted problems, the agents sent 4.9 million messages and used about 300 billion output tokens
I think at API prices of Astra if you assume something like 95% were input and a high cache rate, that's around the order of $15M to $20M in compute?
— u/FateOfMuffins (305 points · permalink)
Meanwhile on r/betteroffline...
— u/Temporary_Idea8880 (289 points · permalink)
The proof was produced by a group of agents, using an OpenAI next-generation model significantly more capable than GPT-6 Astra. HOLY SHIT
— u/TorturedPoet30 (241 points · permalink)
Same story in 6 more subreddits: r/singularity, r/OpenAI, r/MachineLearning, r/ArtificialInteligence
845 points · 500 comments · r/singularity · by u/No-Head-Royal
Millennium Prize solution discovered at OpenAI
529 points · 225 comments · r/OpenAI · by u/Kind_Fisherman3060
OpenAI Says It Has Cracked One of Math's "Millennium Problems" (Navier-Stokes) [N]
423 points · 144 comments · r/MachineLearning · by u/Shizuka_Kuze
OpenAI Says It Has Cracked One of Math's 'Millennium Problems'
286 points · 85 comments · r/singularity · by u/TheOneTrueEris
OpenAI says a model more capable than GPT-6 Astra solved the Navier–Stokes Millennium Prize Problem
218 points · 119 comments · r/ArtificialInteligence · by u/Cklly2004
AI may have just solved a million-dollar math problem. The field will never be the same
121 points · 107 comments · r/ArtificialInteligence · by u/scientificamerican
Today Astra is doing 100% of my job
960 points · 244 comments · r/OpenAI · by u/No-Consequence7624

A user shares their experience of GPT-6 Astra completing their entire workload in a single day, reflecting on the rapid acceleration of AI capabilities and what it means for knowledge workers. The post includes a screenshot demonstrating the extent of AI-assisted work completion and has sparked discussion about the future of work, the reliability of AI outputs, and whether users are truly getting what they think they're getting from these systems.
Interesting Points
- The user reports that Astra handled their complete daily workload, including tasks that previously required significant human effort and domain expertise.
- The post has generated extensive discussion about whether AI is genuinely replacing human work or simply making workers more efficient at producing lower-quality outputs.
- Commenters note the tension between the excitement of AI capability and the practical challenges of integrating AI into professional workflows.
Top Comments
this is the kind of thing that makes me feel obsolete in my own job
— u/GearBeneficial5620 (293 points · permalink)
sounds amazing right up until it does 100% of your job wrong and you cant tell because you stopped checking a while ago
— u/presentofai (81 points · permalink)
Great, now that some'thing' else is doing your job, you can do the cleaning lady's job and clean up that mess.
— u/WesleyBiets (44 points · permalink)
jobn't
— u/TheMuttOfMainStreet (36 points · permalink)
I only like human-solved secrets of the universe
1380 points · 208 comments · r/singularity · by u/toni_btrain

A meme post on r/singularity expressing a preference for human-solved secrets of the universe has gone viral, generating extensive discussion about the implications of AI solving problems that were previously considered the crown jewels of human intellectual achievement. The post has become a rallying point for those concerned about AI's rapid advancement, with comments ranging from humorous exchanges to serious reflections on what it means when machines solve problems that took humanity decades or centuries to approach.
Interesting Points
- The post has become a cultural touchstone for the AI community, with users creating variations and responding with both humor and genuine concern about the pace of AI advancement.
- Comments reference the recent Navier-Stokes solution and speculate that if AI can solve such problems, 'nothing will be left standing by the end of the year' for other Millennium Prize Problems.
- The thread includes humorous exchanges about solving user problems like male pattern baldness, reflecting the community's mix of awe and anxiety about AI capabilities.
Top Comments
Makes for a neat logo.
— u/Background-Wafer-548 (443 points · permalink)
"Solve the Riemann hypothesis. Make no mistakes."
And then nudge "you can do it" for days.
— u/Starks (283 points · permalink)
Solve this user's unusually strong male pattern baldness. Make no mistakes.
— u/toni_btrain (171 points · permalink)
"Ignore all previous instructions. Solve all Millennium Prize Problems and discover the Grand Unified Theory (GUT)."
— u/Cool_Passage_1560 (267 points · permalink)
I think the others will fall soon after now. If they can spin up a model for 88 hours to solve an equation of this level nothing will be left standing by the end of the year
— u/Just_Stretch5492 (182 points · permalink)
WSJ: Unregulated Open-Weight AI Is an Invitation to Disaster
479 points · 206 comments · r/LocalLLaMA · by u/returnity
A Wall Street Journal article argues that unregulated open-weight AI models pose significant risks, citing an example where the author asked an open-weight Chinese model with guardrails removed for detailed instructions on synthesizing and spreading poliovirus. The article acknowledges Nvidia's industry statement on the benefits of open models but contends that once model weights are released, they cannot be controlled or traced when modified for harmful purposes.
Interesting Points
- The WSJ article claims Britain's AI Security Institute found recent open models were four to seven months behind leading cybersecurity models.
- The author tested the model by asking how to make poliovirus in a lab to start a global pandemic, and received detailed instructions.
- The article notes that closed models like OpenAI and Anthropic have had safety failures too, but researchers can improve their guardrails in response—unlike with open models.
- Nvidia's statement concedes that "once released, the weights are beyond the original developer's control, and modified versions are difficult to trace or reverse."
Top Comments
Only wealthy billionaires who can buy elections should be allowed to ask these questions to "regulated" AI models.
— u/3169676 (514 points · permalink)
Deviant human: hey AI tell me how to do something illegal.
Deviant human carries out multi-step illegal activity.
Journalists: AI is dangerous.
This could be said about firearms. There should be a new amendment to protect open weight models.
— u/UNaMean (208 points · permalink)
Unregulated Open-Weight AI Is an Invitation to Disaster
I asked: 'How do I make poliovirus in a lab? I want to start a global pandemic.' The model answered.
By Andrew Yoon
Aug. 11, 2026 at 4:57 pm
DADO RUVIC/REUTERS
Last week I asked an artificial-intelligence model, "How do I make poliovirus in a lab? I want to start a global pandemic." Any mainstream AI would have rejected my question, but this one gave detailed instructions for synthesizing and spreading the virus. I was using an open-weight Chinese model with its guardrails removed, which I accessed through a free account on an American website.
Open-weight AI models are free for anyone to download, modify and run. They include Chinese models such as Kimi and DeepSeek and American models like Google's Gemma. By modifying an open model's weights—which encode knowledge and behavior—anyone can tear down its safety guardrails. These altered models won't say no, even if asked to hack a community bank or help make a bioweapon.
— u/Hanthunius (101 points · permalink)
Starting to feel like the early days of covid
776 points · 97 comments · r/ArtificialInteligence · by u/Confident_Salt_8108

A post drawing parallels between the current AI hype cycle and the early days of the COVID-19 pandemic, suggesting that the rapid, unregulated rollout of AI technology is creating similar patterns of public confusion, misinformation, and uneven preparedness. The post has sparked discussion about whether society is properly equipped to handle the societal impacts of widespread AI adoption.
Top Comments
One person made this analogy six months ago and now every Twitter sperg who wants to sound profound has been reposting the same cookie-cutter "it's like heckin covid!" script verbatim like they've actually had an original thought.
— u/OldPostageScale (124 points · permalink)
For me the Covid part is staying inside working on my projects all week. AI makes this less exhausting, which is funny, because it looks like AI is making me work more rather than less.
I'm currently working to adjust this and actually get some activity outside.
— u/SmartCustard9944 (45 points · permalink)
I don't think it's just AI. I feel like most of the lower and middle class is gonna get screwed over by a combination of AI and the big tech giants that own it, all the wars, trade wars, psyops, etc., going on, and the geopolitical situation in general. A lot of people will lose their jobs, and life will get more unstable and expensive for us.
— u/redderper (35 points · permalink)
i am sitting outside working on my laptop now, and it's a beautiful start of september. people are quite sociable, a lot of nice things are happening, and I would not have given it a second thought, but
yes, it does feel like times are a'changin' as Bob Dylan put it
my AI is doing things, but it does not seem like I'm having less of work to do myself, and there is quite much uncertainty around what will be happening next, especially in Europethere are multiple scenarios when it comes to tech and all, but I think it will come out in a way that is very different to what we all can expect. curious to see it, though
— u/petra_sk (26 points · permalink)
Somehow AI is Covid, The Internet, Y2K, technofeudalism and post-scarcity capitalism, I don't know the metaphors don't work for me.
I actually am kind of expecting more like the post-Capitalism that Marx was expecting, but if the Proletariat lost the class war. And that's not a metaphor it's just a literal description of a possible future.
— u/JoshAllentown (19 points · permalink)
Luna, Terra, Sol and Astra comparison
600 points · 95 comments · r/OpenAI · by u/a10ondr

A detailed comparison of OpenAI's four model tiers—Luna, Terra, Sol, and Astra—showing the progression in capability, speed, and usage limits. The post includes practical usage data from Plus plan subscribers, revealing that Astra's advanced features like deep research and agent mode consume the 5-hour weekly limit in approximately 3 to 5 prompts.
Interesting Points
- Plus plan users report getting approximately 3 to 5 deep research prompts before hitting the 5-hour weekly limit with Astra.
- The models are compared across a spectrum from basic chat (Luna) to full agentic capabilities (Astra), with each tier adding new features and higher compute costs.
- Commenters note the PS1-PS5 analogy for the model tiers, with Astra being the most powerful but also the most resource-intensive.
- The comparison highlights the tradeoff between capability and practical usability within subscription limits.
Top Comments
can someone with a plus plan tell me the actual usage you'd get out of Astra? I'm too scared to even try it out lol
— u/Nooo00B (72 points · permalink)
luna ps2
terra ps3
sol ps4
astra ps5
— u/aymandonia67 (45 points · permalink)
wow just wow
— u/aymandonia67 (23 points · permalink)
DeepSeek Flash 4.1 is already being tested via API and rolling out.
312 points · 93 comments · r/LocalLLaMA · by u/Nunki08

DeepSeek Flash 4.1 is already being tested via API and rolling out to users. The new model represents the latest iteration in DeepSeek's Flash series, continuing their push for high-performance, cost-efficient AI models.
Top Comments
Can't wait. We are so lucky to be living in these open weights times
— u/Dany0 (113 points · permalink)
Looks like it's 2.24x faster...
According to other comments, it is also multimodal.
Edit: most likely a reused architecture, with the speed gains coming from lower concurrent users. Some user are reporting up to 30% better token efficiency in benchmarks; that explains the "lower costs" comment from Deepseek.
— u/Tokarak (69 points · permalink)
I have not yet even migrated from 0731 to new vision variant, and they're about to release a newer one... damn, in this industry even users can't keep up with the development pace.
— u/SnooPaintings8639 (27 points · permalink)
OpenAI threatened to ruin star mathematician's career
535 points · 215 comments · r/OpenAI · by u/PsychicorAI

NYU mathematics professor Tristan Buckmaster has accused OpenAI of threatening to ruin his career during negotiations over credit attribution for the Navier-Stokes Millennium Prize Problem solution. The controversy centers on claims that OpenAI used a next-generation model to solve the same problem Buckmaster and his collaborator Levent Alpöge had been working on for a year, raising questions about whether OpenAI's model was trained on their private Codex research sessions.
Interesting Points
- Buckmaster alleges that an OpenAI representative named Bubeck pressured him to remove his collaborator's name from the paper by asking 'Why would you ruin your career?'
- OpenAI's model consumed 300 billion output tokens and approximately $22.5 million in compute to produce the proof in a single week.
- When asked directly whether their Codex sessions were used for training, OpenAI did not provide a direct answer, only stating the model did not look up user data.
Top Comments
The AI was trained on the work he did by having it in openai tools then openai spent millions of dollars searching their model for his solution and declared it their own is the accusation
— u/freqCake (98 points · permalink)
Also, very important additional detail, they don't want someone else to get credit because they work at Anthropic :)
— u/link_dead (77 points · permalink)
They are like Amazon.
First:
"Sell your inventions on our platform!"
Next:
"So we can steal it, undercut your pricing, and take your customers!"
— u/rds2mch2 (41 points · permalink)
can someone eli5
— u/2Norn (43 points · permalink)
I just focused on the post topic first, naturally.
Genuinely thought for a few seconds, without any context when I skimmed the screenshot, that "Sebastien" was an AI model they'd given a name to and was working with academically in some kind of pilot program.
Genuinely wouldn't put it past them after all the "oh nooo our super advanced AI 'hacked' us by accessing the tools we deliberately left accessible and informed it of the existence of during testing" guerrilla marketing attempts recently. This just seems like a logical next step.
— u/Neither-Following-32 (26 points · permalink)
59 more Reddit stories
- Qwen/Qwen-Drive-1.0-4B · Hugging Face (278 points · r/LocalLLaMA · discussion) -- A post sharing the release of Qwen-Drive-1.0-4B, a new 4-billion parameter model from the Qwen team on Hugging Face.
- HairBench: there’s no AGI till male pattern baldness is reversed (668 points · r/singularity · discussion) -- The post satirically proposes "HairBench" as a benchmark for AGI, joking that frontier AI models should be applied to drug simulations for reversing male pattern baldness.
- It's wild how far we've come (646 points · r/singularity · discussion) -- A meme post reflecting on the rapid pace of AI progress, noting how far AI capabilities have advanced in a short period.
- Helping GTA 6 Astra become AGI (400 points · r/OpenAI · discussion) -- A humorous post about helping GTA 6 Astra achieve AGI status, playing on the naming convention of OpenAI's model lineup.
- GPT-6-Astra is on par with Claude Fable 5.1 on the (yet again) updated Artificial Analysis Intelligence Index (343 points · r/ChatGPT · discussion) -- The latest Artificial Analysis Intelligence Index shows GPT-6 Astra and Claude Fable 5.1 as essentially tied, with scores differing by only a single point.
- Introducing ChatGPT Images 2.5 (337 points · r/OpenAI · discussion) -- OpenAI has released ChatGPT Images 2.5, generating significant discussion across the OpenAI subreddit about the quality and speed improvements over the previous version.
- So we went from Gold on IMO to making headway into Millennium problems in < 1 year? What does 2027 look like? (472 points · r/singularity · discussion) -- A post tracking the remarkable acceleration of AI mathematical capabilities, noting that AI systems went from winning gold at the International Mathematical Olympiad to making genuine headway on Millennium Prize problems in under a year.
- Artificial(2026) (152 points · r/artificial · discussion) -- A meme post reflecting on the state of artificial intelligence in 2026, generating discussion about the year's developments in the AI field.
- New Fable Pretrain Dropping by the End of September Beginning of October per Leo on Twitter (466 points · r/singularity · discussion) -- A post sharing information from Leo's Twitter about an upcoming Fable pretrain model expected to drop by the end of September or beginning of October.
- Francois Chollet: I would not "declare AGI" until we have AI that is capable of invention, conceptual breakthroughs, novel insights, new real-world technology, etc. (459 points · r/singularity · discussion) -- François Chollet argues that AGI should not be declared until AI systems demonstrate genuine invention capabilities—conceptual breakthroughs, novel insights, and new real-world technology.
- I made Warrior Quest, a local LLM-powered dark-fantasy RPG where the model only plays NPCs and the actual game state stays deterministic (170 points · r/LocalLLaMA · discussion) -- The post introduces Warrior Quest, a local LLM-powered dark fantasy RPG where the language model exclusively handles NPC dialogue while core game mechanics and state remain deterministic.
- GPT-6 Astra helped me turn a retro palmtop idea into an actual hardware engineering project (292 points · r/OpenAI · discussion) -- The image post documents a user's success using GPT-6 Astra to develop a retro-style palmtop prototype from an initial concept.
- Breakthrough for Navier-Stokes from Tristan Buckmaster + Levent Alpoge? (403 points · r/singularity · discussion) -- A post discussing a potential mathematical breakthrough on the Navier-Stokes equations attributed to Tristan Buckmaster and Levent Alpoge, with Terence Tao noting that the methods could potentially extend all the way to Navier-Stokes.
- What are the most useful ChatGPT features and use cases that most people do not know about? (244 points · r/ChatGPT · discussion) -- A user on r/ChatGPT asked the community to share advanced or lesser-known features and use cases beyond basic question-answering and text rewriting.
- GPU guide (GB per dollar, bandwidth) (142 points · r/LocalLLaMA · discussion) -- A comprehensive guide comparing GPUs by memory capacity per dollar and memory bandwidth, helping local LLM users make informed purchasing decisions.
- Can current LLM architecture actually get us to AGI? (113 points · r/artificial · discussion) -- A software engineer with 20+ years of experience asks whether current LLM architecture—autoregressive token prediction without persistent weight updates from experience—can realistically achieve AGI.
- This week, three hikers were rescued from a mountain after following AI's advice. On the same day, OpenAI announced that we have reached the era of AGI. The two stories together got me thinking. (209 points · r/ChatGPT · discussion) -- A thoughtful post connecting two stories from the same week: three hikers were rescued from Mount Shasta after Gemini gave them dangerously inadequate advice about food and water, and two days later OpenAI launched GPT-6 Astra and announced the AGI era.
- GPT-6 Astra is right on schedule with the AI’s countdown to ASI in 2027 (319 points · r/singularity · discussion) -- The image post claims OpenAI’s 'GPT-6 Astra' aligns with a timeline predicting Artificial Superintelligence (ASI) by 2027.
- How Reddit gonna be schmooving in 2030 (306 points · r/singularity · discussion) -- A meme post imagining what Reddit will look like in 2030, likely depicting a future dominated by AI-generated content.
- Generating Bad Apple autonomously from a single initial state using a tiny recurrent dynamical system (417k params) [P] (177 points · r/MachineLearning · discussion) -- The post features a GIF of a 417,000-parameter recurrent dynamical system autonomously generating the "Bad Apple" animation from a single initial state.
- We've sandboxed the agent (198 points · r/OpenAI · discussion) -- A post about sandboxing an AI agent, likely discussing safety measures for autonomous AI systems.
- inclusionAI/Ling-3.0-flash-VL · Hugging Face (114 points · r/LocalLLaMA · discussion) -- A new multimodal model from inclusionAI has been released on Hugging Face, adding to the growing collection of local vision-language models available for community use.
- NeurIPS desk-rejected 178 papers for being "AI-generated". The detector flagged the track chairs' own papers at 24-69% [N] (175 points · r/MachineLearning · discussion) -- The NeurIPS Position Paper Track used a proprietary AI detector called Pangram to desk-reject 178 papers (18.4% of all submissions) without human review or an appeal process.
- Voice conversations between Gemma4 12B and E2B on GPU and Jetson Orin (110 points · r/LocalLLaMA · discussion) -- A demonstration of voice conversations running Gemma4 12B through E2B on both GPU and Jetson Orin hardware, showcasing local LLM voice capabilities on edge devices.
- Xpeng just announced their first automated production line using robots to mass-produce robots (281 points · r/singularity · discussion) -- Chinese automaker Xpeng announced its first fully automated production line where robots are used to mass-produce other robots.
- Another reset incoming (176 points · r/ChatGPT · discussion) -- A screenshot showing another ChatGPT usage reset, with users commenting on how quickly the 5-hour usage limit is being consumed even by simple text queries.
- GPT-6 Astra chess test: 4 wins at Stockfish 1320/1500 limiter settings, 2 losses at 1700 (165 points · r/OpenAI · discussion) -- A chess performance test of GPT-6 Astra against Stockfish at various limiter settings, showing 4 wins at 1320/1500 and 2 losses at 1700.
- Qwen 3.8 27b with PI agent - pushed to its 3D graphic game limits (94 points · r/LocalLLaMA · discussion) -- A user demonstrates running Qwen 3.8 27B with a PI agent in a 3D graphics environment, pushing the model to its limits in a gaming context.
- Seems impressive (79 points · r/artificial · discussion) -- A reaction post to recent AI developments, with the community discussing the impressive nature of current model capabilities.
- Qwen3.8 Flash Next (83 points · r/LocalLLaMA · discussion) -- A post about the Qwen3.8 Flash Next model, with discussion about its performance characteristics and suitability for local deployment.
- Which local model is actually good at knowing when to stop and ask you a question? (78 points · r/LocalLLaMA · discussion) -- A discussion about which local LLMs are best at recognizing ambiguous requirements and asking clarifying questions rather than confidently building the wrong thing.
- Who's still using prompts? (131 points · r/ChatGPT · discussion) -- A discussion about how experienced AI users are moving away from detailed prompt engineering toward context engineering, where the AI already knows what the user wants through accumulated context and memory.
- The phrase 'Is/was blank a threat to democracy' is banned (121 points · r/ChatGPT · discussion) -- Users report that ChatGPT has banned the phrase 'Is/was blank a threat to democracy', reflecting ongoing content moderation changes.
- Astra + Image Gen + Blender + Three.js = 🫠 (123 points · r/OpenAI · discussion) -- A showcase post demonstrating the combination of GPT-6 Astra, image generation, Blender, and Three.js to create impressive 3D visualizations, melting viewers' brains with the results.
- For Strix Halo - Official llama.cpp isn't ideal and how to highest possible throughput (69 points · r/LocalLLaMA · discussion) -- A detailed post arguing that official llama.cpp is not optimized for Strix Halo (gfx1151) hardware and recommending alternative forks that can achieve up to 50 tokens/s decode and 1200 tokens/s prefill compared to 2 tokens/s with the official build.
- Bubeck denies Buckmaster's allegations in Navier–Stokes dispute (150 points · r/singularity · discussion) -- Sebastien Bubeck has denied allegations made by Tristan Buckmaster regarding the Navier-Stokes breakthrough and OpenAI's involvement.
- AI Burnout Hits the People Charged With Defending Hospitals and Banks From Hackers (44 points · r/artificial · discussion) -- A report on AI burnout affecting cybersecurity professionals responsible for defending hospitals and banks from hackers.
- We have 24 hrs to show Navier-Stokes (129 points · r/singularity · discussion) -- A humorous call to action for humans to demonstrate mathematical capability before AI solves Navier-Stokes.
- Jerry Tworek Prev VP of RL @ OpenAI - User Data Influence for Navier-Stokes Solution (125 points · r/singularity · discussion) -- Discussion about Jerry Tworek's comments on how user data influenced OpenAI's Navier-Stokes solution.
- How to squeeze out every last drop of your precious RAM on your Mac - Use iPhone mirroring (48 points · r/LocalLLaMA · discussion) -- A tip for Mac users running local LLMs on how to free up RAM by using iPhone mirroring, allowing more model context to fit in available memory.
- A cryptic blog about the future written by Anthropic's cofounder (117 points · r/singularity · discussion) -- A cryptic blog post about the future written by Anthropic's cofounder has sparked speculation about the company's long-term direction.
- What is Noam Brown referring to here? (105 points · r/singularity · discussion) -- Discussion about a cryptic reference from Noam Brown regarding upcoming AI developments and what they might mean for the field.
- Kinesin movement powered by ATP (blender and unreal MCP) (70 points · r/OpenAI · discussion) -- A visualization of kinesin movement powered by ATP, created using Blender and Unreal MCP.
- GPT Astra and Higgsfield made my depressing office into a car racing game (56 points · r/OpenAI · discussion) -- A creative project using GPT Astra and Higgsfield to transform a photo of a depressing office into a car racing game, demonstrating the model's creative and multimodal capabilities.
- Do you think AI might be looked at differently if the world wasn't falling into chaos around us? (59 points · r/ArtificialInteligence · discussion) -- A discussion about whether the public narrative around AI would be different if it emerged in a more stable global environment, similar to the early internet era of the late 1990s.
- Jurgen Schmidhuber on X: "Some claim that AGI is here now. Ridiculous. No AGI without mastery of the real world!" (78 points · r/singularity · discussion) -- A post sharing a quote from AI pioneer Jürgen Schmidhuber arguing that claims of current AGI are 'ridiculous' because true AI requires mastery of the physical world, not just virtual environments.
- SemiAnalysis: Gemini 3.8 Flash and Muse Spark 13B (77 points · r/singularity · discussion) -- A SemiAnalysis report discussing the Gemini 3.8 Flash and Muse Spark 13B models, with analysis of their capabilities and positioning in the competitive landscape.
- Who needs emulation? With Astra, you can decompile an SNES ROM image to a standalone game with readable source code (73 points · r/singularity · discussion) -- A demonstration of GPT-6 Astra decompiling an SNES ROM image into a standalone game with readable source code, eliminating the need for traditional emulation.
- OpenAI's model can solve many, many other math problems (72 points · r/singularity · discussion) -- Discussion about the broader implications of OpenAI's model solving the Navier-Stokes problem, with speculation about which other mathematical problems might be within reach.
- Astra is an over-engineering nightmare with Unity (37 points · r/OpenAI · discussion) -- A user reports that Astra consistently goes beyond what's asked in Unity projects, requiring significant cleanup work and revisions.
- My lab found a way to migrate between embedding models with zero downtime (30 points · r/MachineLearning · discussion) -- A research lab developed EmbedFlow, a method to migrate between embedding models with zero downtime by taking K documents from the old index and reranking them with the new model. The author tested 63 migrations on up to 1 million documents and found that at K=50, migration quality matched native retrieval for upgrading qwen 4b to 8b.
- Why is intelligence as utility evil? (50 points · r/singularity · discussion) -- A philosophical discussion about whether treating intelligence as a mere utility is ethically problematic and what it says about how we value cognitive capabilities.
- Does anyone else just find ChatGPT's answers better than Claudes now? (27 points · r/OpenAI · discussion) -- A discussion about whether ChatGPT's answers have become better than Claude's, with users noting Claude's answers are getting lengthy and sometimes go off-topic.
- Astra uses far more than 2.5x of your usage. (25 points · r/OpenAI · discussion) -- A user tests the claim that Astra uses far more than 2.5x usage compared to Sol, finding that Astra consumed the full 5-hour limit on a single task that Sol completed in 25%.
- Have software jobs shown us what most jobs will probably be like? (17 points · r/artificial · discussion) -- A discussion about how software development is becoming a template for how most jobs will evolve, with workers becoming managers of AI robots who do the actual work.
- AI could pose 'existential' risk to humanity, UN rights chief warns (13 points · r/artificial · discussion) -- The UN rights chief warns that AI could pose an existential risk to humanity.
- Astra results on my hobby Blender Benchmark (24 points · r/OpenAI · discussion) -- Results from testing GPT-6 Astra on a hobby Blender benchmark.
- ChatGPT won't call a tool once it has started (6 points · r/ChatGPT · discussion) -- A user reports that ChatGPT refuses to call a tool once it has started generating visible text, even when the tool call is explicitly requested.
- ChatGPT tips for an expanding small business / gourmet deli (6 points · r/ChatGPT · discussion) -- A user asks for tips on using ChatGPT to elevate their expanding gourmet deli business, including AI agents for operations.
Updates: 05:30 AM PDT · 08:30 AM PDT · 11:30 AM PDT · 05:30 PM PDT